
Reading width
Wide uses the full column for everything, text, diagrams, code, and exercises. Narrow keeps the standard reading width.
Text size
Scales the body text. Headings and code blocks keep their size.
In this section
Microsoft 365 Recovery Windows: Mail, Files, Users, Groups and Policies
Introduction
Microsoft 365 has no single backup and no single restore button. What it has is a collection of safety nets, each built into a different service, each catching a different kind of loss, and each with its own time limit. Deleted mail sits in one place for one period, deleted files in another for another, deleted users and groups in a third. Some losses have no safety net at all.
None of them is a backup in the traditional sense, because each keeps its copies inside the same tenant the attacker may control, and an administrator can empty most of them. Organizations that need protection against that use a separate backup service, and the investigation should know whether one exists.
Each safety net has its own window, counted from the loss, not from discovery. A hold or retention policy extends the mail and Teams rows; nothing extends the red ones.
Most of these mechanisms were designed for ordinary mistakes: a user deleting the wrong folder, an administrator removing the wrong account. They work for incidents too, provided somebody knows they exist and uses them before their windows close. The commonest recovery failure is not a missing mechanism but a missed deadline.
This lesson covers recovery as distinct from undoing an attack, then each mechanism in turn: mail, files, identities and groups, Teams, and configuration. It ends with what no mechanism can recover, which is the part that most shapes what an organization tells people after an incident.
Recovery Is Not Undo
Restoring data without restoring the attackerRecovery means returning the business to working order: the mail, files, accounts and settings people need, in a state that can be trusted. It is tempting to think of it as reversing everything the attacker did, and that framing causes two kinds of mistake.
The first is restoring too much. A mailbox restored to its state before the attack can bring back the attacker's inbox rule along with the deleted messages. An account restored from deletion returns with its group memberships and application grants intact, including any the attacker added. A file library rolled back to last week's state undoes a week of legitimate work along with the damage.
The second is restoring too early. Recovery done before containment is finished gives the attacker the restored data too. A restore that brings back a compromised account before its authentication methods are cleaned can reopen the door that containment closed.
The recovery order. Restoring before containment hands the attacker the restored data; restoring a whole state brings back their changes.
The order is the core of Module 10, and every mechanism below is described with it in mind.
A useful test before any restore is to ask what the restored object would let the attacker do if they still had access. If the answer is anything at all, containment is not finished, and the restore waits. Each has a window, and each window starts counting at the moment of loss, not the moment of discovery, which is why recovery planning starts while the investigation is still running.
Applied to the finance mailbox, that test turns a broad request into a narrow one:
Restore request, checked before approval
Prepared exampleWhat a whole-state restore would have risked
- Every change since 26 February discarded, the user's own included
- Nothing gained against the attacker: Archive-2026 and the forwarding were removed in containment
- The selective restore brings back only what was lost, and the rules are checked after it
Choosing what to restore is itself an investigative question, and it uses the same records. The audit log says what was deleted, changed or encrypted, by whom and when, and that list is the recovery scope. Restoring from that list rather than from a point in time is slower to plan and much safer to carry out, because it brings back exactly what the attacker took away and nothing the attacker added.
Deleted mail in Exchange Online passes through stages. A message deleted normally goes to the Deleted Items folder, where the user can see and restore it. When it is removed from there, or deleted with Shift+Delete, it moves to the hidden Recoverable Items folder. Users can still restore from Recoverable Items through Outlook's recover-deleted-items feature, and administrators can search it.
Recoverable Items keeps deleted messages for the mailbox's deleted item retention period, which is fourteen days by default and can be raised to thirty. After that they are purged, unless a hold or retention policy preserves them, as lesson 0.4 described. A hold placed on day ten keeps what is still there; a hold placed on day twenty, on a mailbox with the default setting, keeps nothing deleted in the first six days.
Attackers delete mail for specific reasons: to hide a reply that would expose a fraud, to remove a security notification, or to cover a sent message. Spotting deletion that is not ordinary housekeeping starts with knowing what ordinary looks like, and the audit log's HardDelete operation, which records items being permanently removed, gives a baseline:
OfficeActivity
| where Operation == "HardDelete"
| summarize Deletes = count() by UserId, Day = bin(TimeGenerated, 1d)
| summarize Typical = percentile(Deletes, 50), Highest = max(Deletes)
In the course dataset the typical user-day with any permanent deletion has one, and the highest in the whole month is two. Against that baseline, an account that permanently removed thirty items in an hour would stand out immediately, and the window for recovering those items would be known from the mailbox's retention setting.
The recovery itself is undramatic. Items still in Recoverable Items, or preserved by a hold, are found with a content search and restored to the mailbox or exported. The investigation should capture them first, because a deleted reply that exposes a fraud is evidence before it is recovered mail.
Whole mailboxes have their own window. When a user account is deleted, its mailbox is soft-deleted too and can be recovered for 30 days by restoring the account. If the mailbox was on hold when the account was deleted, it becomes an inactive mailbox instead, kept for as long as the hold lasts and searchable throughout. That distinction matters when an attacker with administrative access deletes accounts: a mailbox on hold survives indefinitely, one without a hold has a month.
Files
Recycle bins, versions and restoring a whole librarySharePoint and OneDrive give files three overlapping safety nets, and together they cover most kinds of damage.
Three safety nets for files, read left to right. Files Restore is built on versions, so lowering version limits weakens it.
The recycle bin handles deletion. Version history handles modification: a file overwritten with nonsense, or encrypted by ransomware running on a synchronized laptop, still has its earlier versions, and those versions are what make cloud files far easier to recover than files on a local disk. Restoring to an earlier time handles damage at scale, where thousands of files were changed at once and restoring them one by one is not practical.
Ransomware is the case where these matter most. Ransomware running on an endpoint encrypts the local copies of synchronized files, and the sync client faithfully uploads the encrypted versions to OneDrive or SharePoint. The cloud copies are now encrypted too, but each one's previous version is the clean file, and a library restore to a moment before the encryption started brings them all back.
The bulk restore is also where restoring too much bites. Rolling a library back to before the attack discards every legitimate change made since, so the restore point is chosen from the audit records, as close as possible to the first malicious change, and the work done after that point is identified and redone. The audit log's FileModified records give the boundary. In the course dataset no user modifies more than three files in any hour, so a burst of hundreds in minutes would mark the start of damage precisely.
Choosing the restore point is a query, not a guess. The busiest days for file changes are where a mass modification would show:
OfficeActivity
| where OfficeWorkload == "SharePoint" and Operation == "FileModified"
| summarize Modified = count(), Users = dcount(UserId) by Day = bin(TimeGenerated, 1d)
| top 3 by Modified
In the course dataset the busiest day has 41 modifications by 30 people, which is ordinary work rather than encryption. A ransomware day would stand out as one user, or one device, changing far more files than anyone else, and the restore point goes just before its first change.
The heading of Module 10's lesson on files notes that one of the two safety nets is a user setting, and that is worth knowing early. OneDrive users can restore their own OneDrive to an earlier time without an administrator, which is convenient and also means a well-meaning user can roll back past the evidence before anyone has captured it. Recovery and preservation meet here again: capture the state of an affected OneDrive or library before anyone, user or administrator, restores it.
Version limits are the other detail to check. Libraries keep a bounded number of versions, and organizations sometimes lower the limit to save storage. Ransomware that encrypts the same file repeatedly, or a sync loop that saves many times, can push the clean version out of the history if the limit is low. A library's version settings belong on the recovery record for any site that holds important files.
Identities and Groups
Soft deletion and its thirty daysEntra ID soft-deletes many objects rather than removing them immediately. A deleted user, Microsoft 365 group or application registration stays in a deleted state for 30 days, during which it can be restored with its identifiers intact, and after which it is permanently removed.
What a deletion leaves to restore. The audit log writes Delete group for every group type, so the group type decides which row applies.
The object ID matters more than it seems. Permissions, role assignments and policy targeting in Microsoft 365 refer to objects by ID, not by name. A restored user keeps its ID, so the permissions that pointed at it still work. A distribution group recreated with the same name gets a new ID, so every permission, Conditional Access exclusion and access package that referred to the old group silently stops applying, and each has to be found and pointed at the new one.
An attacker who deletes accounts or groups during an incident, to disrupt the response or cover their tracks, is therefore causing damage with a 30-day deadline for most objects and no deadline at all for distribution groups, which simply have to be rebuilt. Cloud security groups used to be in that position too; Microsoft now soft-deletes them, a capability it still labels as preview.
Soft deletion also has an escape hatch that attackers know about. An administrator can permanently delete a soft-deleted object before its 30 days are up, removing the safety net entirely. A deletion followed shortly by a permanent deletion of the same object, recorded as separate operations in the directory audit log, is a strong sign of deliberate destruction rather than an administrator's mistake, and it is one more reason to treat administrator compromises as the most serious kind. The directory audit log records every deletion with its target and actor, and that record is the list recovery works from.
Entra Admin Center
Entra ID › Users › Deleted users
Select the user and Restore user. The Deleted date column shows how much of the 30 days is left; Microsoft permanently deletes the object when it runs out.
The list shows every soft-deleted user with the date it went:
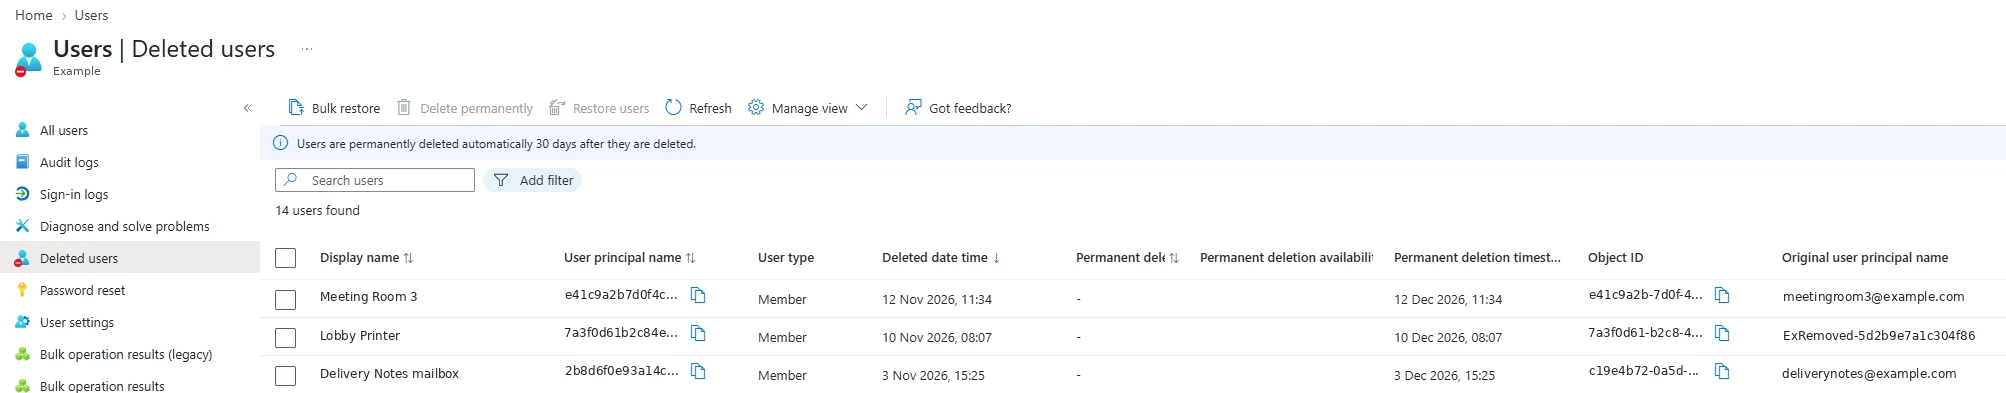
Deleted users, in a different tenant. The permanent deletion date is the restore-by date to put on the incident timeline. Select the image to open it full size.
Restoring a user also restores what the attacker may have attached to it. A restored account comes back with the group memberships and authentication methods it had when deleted, and in an incident those may include the attacker's. The check-what-came-back step in section one applies here more than anywhere. Microsoft Entra Backup and Recovery, where it is available, goes further and can return supported objects and settings to an earlier known-good state, which matters for changes as well as deletions.
Configuration
Policies, settings and the audit log's old valuesConfiguration is the area with the fewest safety nets. Some objects are soft-deleted: deleted Conditional Access policies, for example, can be restored for a period after deletion. But most settings, such as mailbox forwarding, sharing policies, consent settings and a policy's own conditions, have no history and no undo. They are simply in their current state.
For those, the recovery record is the directory audit log. Lesson 0.3 showed that many change records carry modifiedProperties with old and new values, and those old values are what the configuration should be returned to. Listing the policy changes in a period is the first step:
AuditLogs
| where Category == "Policy"
| project TimeGenerated, OperationName,
          Actor = tostring(InitiatedBy.user.userPrincipalName),
          Policy = tostring(TargetResources[0].displayName)
| order by TimeGenerated desc
The course dataset returns five changes over the month. Two administrators updated policies including the one blocking legacy authentication and the one requiring multifactor authentication for all users, one guest policy was added, and on 13 March a policy named "Legacy pilot, superseded" was deleted. Each looks routine, and each is exactly the kind of change an attacker with an administrator session would make to weaken a tenant. Telling routine from hostile depends on the actor's sessions at the time, not the change itself.
In an incident involving an administrator account, every one of these changes in the window has to be checked against its actor, its time and its old values. A policy weakened by an attacker and never noticed is a gap that survives the incident, and recovery is not complete until the tenant's configuration is known to be what the organization intended.
The same applies to tenant-wide settings outside Entra ID: external sharing levels in SharePoint, outbound spam and forwarding policies in Exchange, and the consent settings that decide which applications users can approve. These are changed in other admin centers, recorded in the unified audit log rather than the directory audit log, and easy to miss when the investigation is focused on one account. A recovery checklist that includes them by name is the only reliable way to make sure each one is looked at.
Teams
Built from other services, recovered through themTeams is assembled from other services, and its recovery follows from that. A team is backed by a Microsoft 365 group. Its files live in a SharePoint site, its channel conversations and chats are stored through Exchange, and its membership is the group's membership.
A team is three services, recovered through each one. Messages are the part with no recycle bin.
The last row is the one that surprises people. There is no recycle bin for chat. A message an attacker deleted from a Teams conversation can be found again only if a retention policy or hold was preserving Teams content, and even then it comes back as a search result for the investigation, not as a message reinstated in the chat.
That makes Teams a place where preparation decides recovery entirely. An organization that wants deleted chat to be recoverable decides so in advance, with retention, and Module 2's list of things to turn on before they are needed includes it.
Before promising to recover Teams messages, confirm
ChecklistIn Microsoft Purview
- A retention policy covers Teams chats and channel messages
- Its scope includes the affected users and teams
- It retains rather than only deletes, for longer than the gap since the deletion
- If any answer is no, the deleted messages are gone and the report says so
Team membership is the other Teams-specific recovery question. Because membership is the group's membership, an attacker who added an outside account to a team, or added a compromised account to a sensitive one, made a group change recorded in the directory audit log. Recovery removes those additions and checks the team's guest settings, and the audit record of the addition gives both the time it happened and the account to remove.
What Cannot Be Recovered
And why it shapes what gets saidSome losses no mechanism can reverse, and they are worth naming plainly because they determine what an organization has to tell people.
Four losses no mechanism reverses, each with what it means for the organization. They are what the notification and the report must account for.
The first and last rows matter most. In the course dataset's main incident, mail was forwarded outside the organization from 3 March and an application read the mailbox for a week. Once containment stops both, every message is still in the mailbox, so nothing needs restoring there. But the copies that left are permanently outside the organization's control, and the attacker now knows how the finance team handles invoices. Recovery is complete in the technical sense, and the incident's consequences are not.
That is why recovery feeds back into findings and notifications rather than ending the story. What could not be recovered is often exactly what people must be told about, and it is also what the improvements after the incident should make harder next time.
The tenant records how much of its data could already be outside it in this way:
OfficeActivity
| where Operation == "AnonymousLinkCreated"
| summarize Links = count(), People = dcount(UserId),
            First = min(TimeGenerated), Last = max(TimeGenerated)
127 anyone-with-the-link shares created by 52 people in a month. Each can be removed, and none of them can be recalled once used: whoever opened one already has the file.
Being explicit about this in the recovery report avoids a common misunderstanding. When a business owner hears that everything has been restored, they reasonably assume the incident has no remaining effect. A recovery report that lists, beside what was restored, what was exposed and cannot be retrieved, gives them the accurate picture, and it connects directly to the notification decisions in lesson 0.9.
What Module 10 Builds On It
Recovery as its own phaseModule 10, Recovery, takes each mechanism into practice. It covers why recovery is not undo, the order that stops a restore from re-inviting the attacker, mail as the one window you control, files and the two safety nets, one of which is a user setting, the identity you deleted, Teams and the absence of a restore, retention working against recovery, what cannot be recovered, proving something came back, and who declares the incident over.
The habit to start now is to put every recovery window on the incident timeline as a date, alongside the evidence deadlines from lesson 0.2, the moment the loss is discovered. A deleted distribution group, a purged message and an encrypted library each start a clock, and the restore has to happen before it runs out. A query that lists every deletion recorded in the directory over a period gives the starting list for identities:
AuditLogs
| where OperationName has "Delete"
| project TimeGenerated, OperationName,
          Target = tostring(TargetResources[0].displayName),
          Actor = tostring(InitiatedBy.user.userPrincipalName)
| extend RestoreBy = TimeGenerated + 30d
On the course dataset it returns the deleted Conditional Access policy, with a restore-by date thirty days on, which applies to soft-deleted objects. For a distribution group the deadline column would be meaningless, because there is no soft deletion to restore from, and the row would go straight onto the rebuild list.
Practice
What can still be brought back? prepared evidenceThe prepared evidence below is a list of losses from an incident, with the date each happened and the date the investigation reached it. For each, decide whether it can still be recovered, by which mechanism, and what must be checked before it is handed back.
The second path is to map the recovery windows for a real tenant, so the dates are known before an incident needs them.
- Record each mailbox type's deleted item retention, the default or the raised value, and which mailboxes are on hold.
- Record the library version limits for the sites holding the most important files.
- Check whether a retention policy covers Teams chat and channel messages.
- Run the deletion query in section eight and the policy query in section five against your own workspace, and note anything you cannot explain.
Microsoft 365 recovers through separate safety nets with separate windows: fourteen to thirty days for deleted mail without a hold, 93 days in the file recycle bins, thirty days to roll back a library and to restore soft-deleted users, groups and applications, and nothing at all for distribution groups, unrecorded settings and deleted chat without retention. Recovery comes after containment, restores selectively and checks what came back. What left the organization or was learned by the attacker cannot be recovered, and it is what the organization has to account for.
That completes Module 0. Module 1 starts from the foundations laid here and builds the discipline of Microsoft 365 incident response on them.
Resources
Microsoft revises these pages; where a page and this lesson disagree, the page is newer.